Local AI
309 episodes
#6217: Fine-Tuning a Trillion-Parameter Model at Home
What does it actually take to full fine-tune a trillion-parameter model? Sixteen terabytes of optimizer state, hundreds of GPUs, and a very big bill.
#6216: What Do You Call the Middle Tier Model?
Sonnet, Sol, Flash, Medium — the daily-driver models nobody can name, and why they're squeezed from above and below.
#6212: Woolly Sedate Snail and Other Model Failures
Most of Hugging Face's 2.96M models sit unread. But the dust has a personality — snails, pirates, and a matchbox that resigns.
#6211: Attention Is Still Winning: The Hybrid Model Census
Mamba layers shipped — inside hybrids. A census of Qwen, Nemotron, Kimi, Granite, and why MiniMax went back to full attention.
#6207: Two WERs, One Model: Inside ASR Eval Harnesses
Same model, same audio, two different word error rates. The gap lives in the normaliser — and that's just layer two of three.
#6205: Where Should Your Notebook Actually Run?
Colab's free GPU comes with a 12-hour wall and hidden secrets in your saved outputs. Here's where notebooks should actually live.
#6201: Inside Cloudflare's Clef: A Language Model That Can't Speak
Cloudflare's Clef reads text, images, and video but outputs only probabilities — no words. Here's what's actually under the hood.
#6198: Benchmarking a TTS Model on Your Own GPU
Real-time factor, warm-up artifacts, and why an 8-bit quantized speech model might not run any faster.
#6196: Fine-Tuning ASR: When Your Model Memorizes You
Your fine-tuned speech model aces your training recordings — but does it actually work on fresh audio?
#6194: Teaching a TTS Model His Own Accent
One man fine-tuned a text-to-speech model on his own voice to get Irish-accented English that can say Hebrew words mid-sentence.
#6192: What Actually Happens When You Train a Model
Data in, model out — except the "data" is pairs, the split is the whole game, and one leaked speaker can fake your score.
#6191: What Actually Happens During Fine-Tuning
Sixteen bytes per parameter in, two out — a walk through the forward pass, backward pass, and optimizer that turn a dataset into new weights.
#6190: When Your AI API Quietly Changes Under You
Same API name, different model behind it. How to tell when the thing you tested stops being the thing you're using.
#6188: Every Way Linux Relieves Memory Pressure
Zram, zswap, swappiness, and the OOM killers — the full ladder Linux climbs when RAM runs out, and what to actually run.
#6185: Why AI Labs Sell a Tier Above the Flagship
Fable, Deep Think, SuperGrok Heavy — what the $300/month top tier actually does that the flagship can't.
#6182: Running a Private APT Repo for Family Machines
Daniel wants his Debian packages on family machines without becoming their unpaid update service. Here's the modern way to do it.
#6177: How Voice Cloning Works From Six Seconds of Audio
Six seconds of reference audio is all Chatterbox needs. The real work happened in the half-million hours of training before you showed up.
#6176: Do Audio Models Hear How You Said It?
A benchmark called LISTEN found audio models score near chance when emotion lives in the voice, not the words. What does that mean for real calls?
#6175: Video Models Can't Tell Time: What Motion Benchmarks Reveal
Frontier models score 48% on tasks where humans hit 98% — the gap is motion, speed, and sequence, not scene description.
#6172: Recipes vs. Regeneration: AI Photo Editing in 2026
Two ways AI edits photos now: models that write a readable recipe of slider values, and models that just repaint the whole frame.
#6171: AI Audio Restoration: What Actually Ships in 2026
Noise removal and bandwidth extension are shipping products today. Matching a clip to a target EQ is still mostly a research prototype.
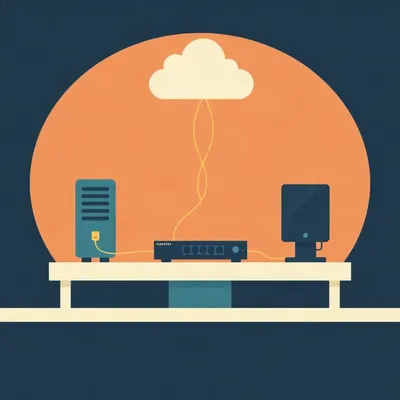
#6170: One Endpoint, Many Boxes: Local LLM Routing
A LiteLLM-style proxy can fail over between your own GPU boxes and the cloud — but it can't see your VRAM.
#6168: Hebrish: Hebrew-Aware Dictation That Actually Works
Two new speech models fix English-Hebrew code-switching dictation — and the whole training run cost about fifty cents of GPU time.
#6163: Forking a Keyboard for One Voice Feature
Daniel built a Hebrew-English dictation engine. Now he wants to fuse it into someone else's keyboard — without inheriting its entire future.